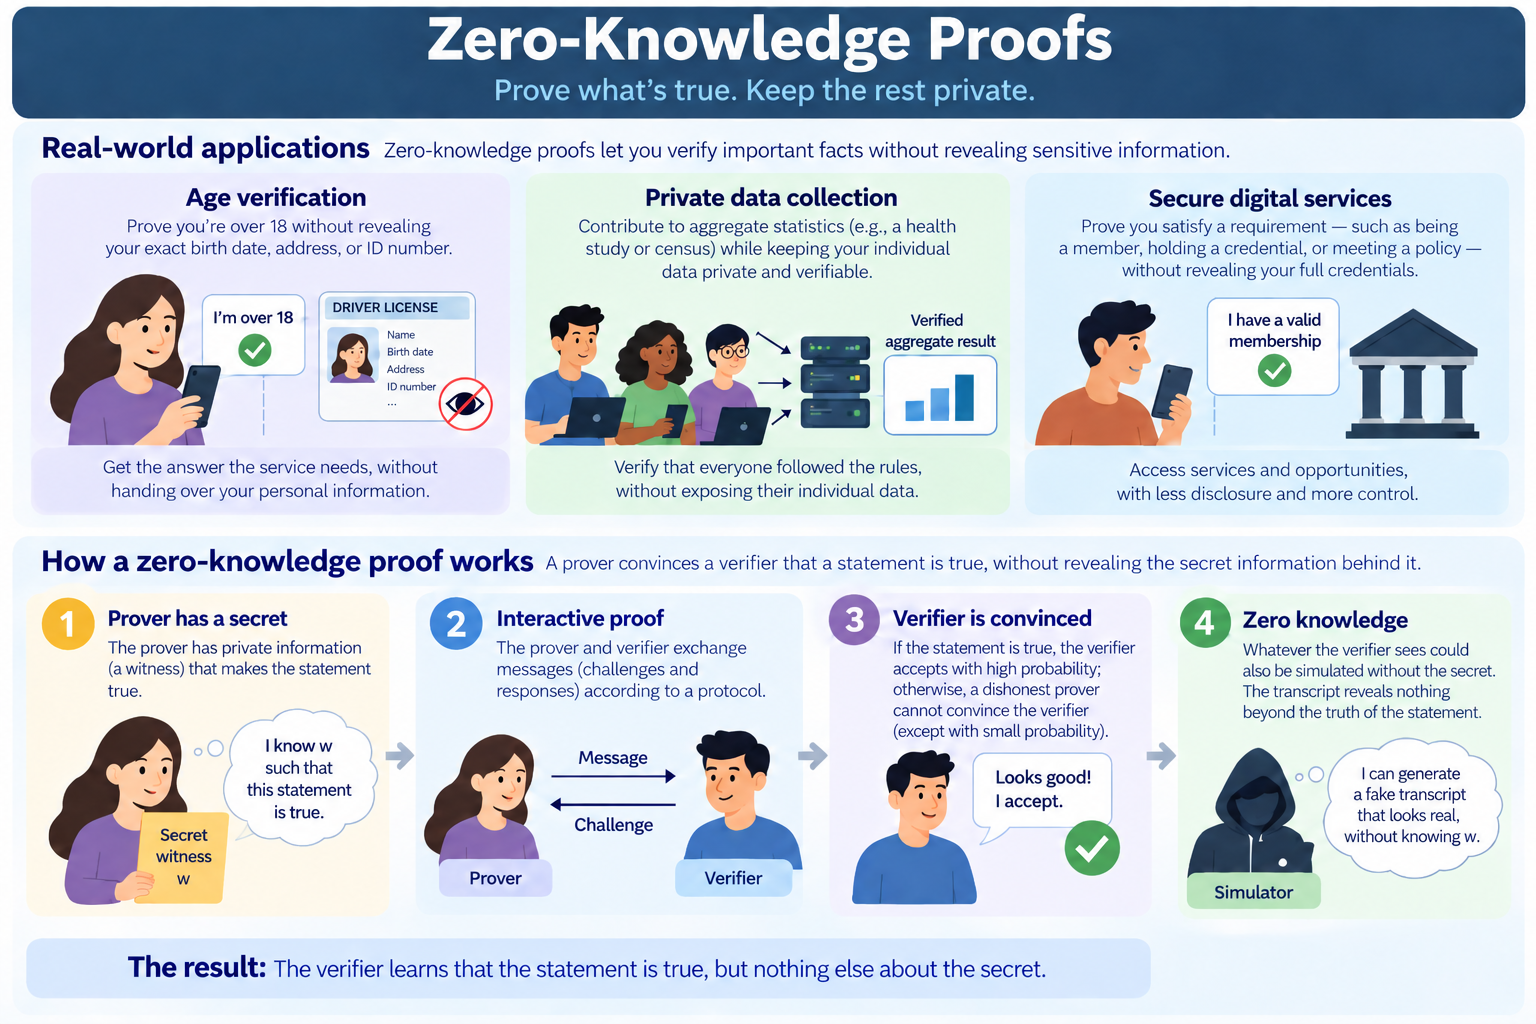
tl;dr Recently, Marshall Ball and I released work on the computational complexity of multiplicative zero-knowledge (MZK), a new definition of zero-knowledge, and its relation to a well-studied definition of zero-knowledge, statistical zero-knowledge (SZK). We show that up to a certain level of leakage, both definitions are equivalent in terms of computational power. That is, allowing (logarithmic) leakage can change how we prove a statement without changing whether the statement belongs to SZK.Then as we allow more leakage, MZK becomes closer in power to IP/PSPACE (i.e., can solve all problems that interactive proof systems can solve). In my class, starting next week, we will begin discussing zero-knowledge definitions and protocols.
Motivations
Suppose a website needs to check that you are over eighteen. One approach is to upload a photograph of your identification. But that may reveal much more than the website needs: your exact birth date, address, photograph, and identification number. However, the question the website needs answered is actually much narrower: Does this person satisfy the age requirement?
Zero-knowledge proofs offer a way to separate that answer from the information used to establish it. A person can prove that an authentic credential satisfies an age requirement without handing over the underlying credential. This is a concrete application of the technology: Google’s digital-identity documentation describes zero-knowledge proofs for verifying claims such as “over eighteen” while minimizing disclosure of credential information.
Here is another example: A service might want aggregate statistics without seeing individual contributions. Yet privacy alone is not enough: malicious participants could submit malformed values that corrupt the result. The system needs to verify that contributions satisfy its rules without exposing them. Prio, for example, combines private aggregation with secret-shared proofs that help protect the computation against malicious clients.
These two applications share a common theme:
How can we verify that someone followed the rules without demanding the private information that makes verification easy?
It turns out that zero knowledge is the right tool! And there are several different definitions that imply a surprisingly rich tradeoff between privacy, efficiency, and computational power.
In a recent work, Marshall Ball and I study whether and how multiplicative relaxation of zero-knowledge (MZK) is related to statistical zero-knowledge (SZK). It turns out MZK can improve efficiency, relative to SZK, without enlarging the class of provable problems but when leakage is at most logarithmic. At larger leakage budgets, we show both conditional and oracle separations, and shows that polynomially bounded leakage eventually recovers the full power of interactive proofs.
Our work was driven by the following questions: Can allowing leakage make a proof cheaper? And can allowing leakage make a fundamentally different kind of statement provable?
First, let’s recall the (high-level) definition of zero-knowledge.
What does “zero knowledge” actually mean?
A proof system has a prover, who tries to prove a public statement, and a verifier, who checks it. A useful system must convince the verifier when the statement is true, while preventing a dishonest prover from successfully proving a false statement (except with a small probability). Zero-knowledge adds a privacy requirement: the interaction should not give the verifier information beyond what it could efficiently generate from the public statement itself.
That last requirement is formalized through a simulator: Imagine a program that receives the public statement but not the prover’s secret evidence (called the witness). The simulator must produce an artificially created record of what the verifier would see during the proof. If that record looks like a real interaction, the verifier has not obtained something that required access to the prover’s secret. Note that the simulator is not discovering the secret nor proving the statement through a genuine interaction. It is manufacturing a record. The difference matters: a real cheating prover must answer challenges as they arrive, while an offline simulator can construct a whole conversation in a different order. A simulator transcript need not be something a prover could generate while interacting with an independently randomized verifier.
Essentially, to prove privacy, we will look at two distributions: 

Different notions of zero-knowledge impose different requirements on how closely these distributions must agree.
Why statistical zero-knowledge?
In statistical zero-knowledge, or SZK, the real and simulated views must have negligible statistical distance. Recall that statistical distance measures the largest difference in probability that the two distributions assign to any event: 
For comparison, computational zero-knowledge requires only that efficient observers/adversaries be unable to distinguish the distributions to gain information. The difference is between information that is statistically absent and information that is computationally inaccessible.
There is also an important difference between privacy and soundness. In complexity theory and cryptography, a proof must remain sound against computationally unbounded cheating provers. On the other hand, an argument only needs to hold against computationally bounded cheating provers. For this blog post, we only consider proofs.
SZK is a class of problems: it is about families of statements that admit proof systems with statistical simulation. Our paper follows the standard formulation, in the literature, using promise problems, where inputs are guaranteed to belong to specified yes- or no-cases.
An example: proving that two networks are different
Two graphs are isomorphic when renaming/relabelling their vertices makes them identical. Now consider the problem of proving that two graphs are not isomorphic. The verifier secretly chooses one graph, randomly renames its vertices, and sends the result to the prover. The prover identifies which original graph was chosen. If the graphs are non-isomorphic, a (powerful) prover can always answer correctly. If they are isomorphic, the challenge has the same distribution whichever graph was chosen, so no prover can guess the hidden choice with probability greater than one half.
For an honest verifier, simulation is straightforward: choose the graph and relabeling, then record the already-known answer. This gives perfect honest-verifier zero-knowledge (which is stronger than statistical distance closeness). Note that this simple protocol does not by itself lead to security against arbitrary cheating verifiers; that requires additional machinery.
A second example: proving that distributions are distinguishable
A more general example is Statistical Difference. The input consists of two efficient randomized programs, with a promise that their output distributions are either close or far apart.
Sahai and Vadhan [4] showed that this problem is complete for SZK: every problem in SZK can be (efficiently) converted into the statistical distance problem. Their work also develops transformations that polarize statistical distance, turning a suitable initial gap into distributions that are almost identical or almost disjoint. In the latter case, a prover can help a verifier identify which distribution generated a challenge sample. In our new paper, we leverage such promise problems to show equivalences (up to logarithmic leakage) between SZK and MZK.
Replacing statistical closeness with multiplicative closeness
Statistical zero-knowledge requires probabilities to agree up to a negligible additive difference. Multiplicative zero-knowledge, or MZK, instead permits a (controlled) multiplicative difference:
For every event 


Here, 


The definition of MZK is, obviously, inspired by differential privacy. But the objects being compared are different. Differential privacy typically compares outputs on neighboring datasets. Here, the comparison is between a real interaction and a simulated interaction. There need not be any neighboring input relation. The relaxation can be substantial even when 


Why relax zero-knowledge at all? Because of savings in communication
A privacy definition is useful partly because of the protocols it enables. Requiring a stronger simulation guarantee can mean sending more information, performing more computation, or using a more expensive interaction pattern.
PINE provides a concrete example. It verifies a norm bound on a secret-shared vector: a useful task when private contributions must be prevented from having excessive influence on an aggregate. Its statistical and differential variants have different communication costs. Under one parameter setting reported in the paper, the additional communication above basic aggregation is:
| Vector dimension | Statistical PINE | Differential PINE |
|---|---|---|
| 10,000 | 22% | 4.77% |
| 100,000 | 3.18% | 1.46% |
| 1,000,000 | 0.49% | 0.32% |
| 10,000,000 | 0.13% | 12.63% |
These results use 

A separation for the same distributed task
In our recent work, we also give a theoretical explanation for the separation in communication costs.
We fix a randomized functionality. Suppose 


Note that this distributed setting is different from the single-prover, public-statement setting used to define SZK and MZK as complexity classes. But this motivates our exploration into MZK: Relaxing simulation can save communication even when the task/function being computed remains the same. But does this always change which problems admit proofs? We provide a negative answer!
A surprise: logarithmic leakage in MZK does not enlarge set of SZK problems
For me, this was surprising! Let 

The honest-verifier class, HVMZK, requires simulation only for the prescribed/honest verifier. MZK requires simulation against every efficient verifier, including verifiers that deviate from the protocol. At logarithmic leakage, both classes coincide with SZK. This is surprising because multiplicative closeness can be much weaker than statistical closeness. (The earlier Bernoulli example already showed that even constant multiplicative leakage permits constant statistical distance.)
How can these facts coexist? Because the theorem is about the existence of proof systems for a problem, not the privacy of a particular transcript distribution. A problem might have a very efficient multiplicative zero-knowledge protocol whose transcripts are not statistically simulatable. The theorem says that the same problem also has some statistical zero-knowledge proof. That is, the statistical zero-knowledge proof may use a different interaction and have different costs. The theorem does not imply that we will preserve the original protocol’s efficiency or statistically simulate its original transcripts.
Why does a logarithm appear?
For some constant 


But an accepting conversation might have been assembled using correlations that a real prover could not create. For example, an early answer correlated with a verifier’s (still-hidden) future randomness. So, finding accepting transcripts therefore does not lead to soundness. We addresses this via a causality constraint using a simulation-based prover and relative entropy. On yes-instances, symmetric multiplicative simulation leads to a logarithmic relative-entropy bound (after suitable regularization). On no-instances, an efficiently sampled distribution that accepts often must be much farther, in relative entropy, from the corresponding genuine online prover’s view, because soundness forces that prover to accept only negligibly often. Then an entropy-chain-rule identity translates this gap into instances of Entropy Difference, while Statistical Difference handles insufficient accepting mass. These are both SZK-complete problems, giving the desired reduction.
Beyond logarithmic leakage
In our paper, we give several ways in which larger leakage budgets permit greater computational power. Some are unconditional class characterizations; some require complexity assumptions; others establish separations in oracle settings.
SAT at linear leakage: an (intentionally) revealing protocol
The SAT problem (which we study in CS/ECE 374 at UIUC!) is about whether a Boolean formula has a satisfying assignment. Let the formula have encoding length 

With probability
, send
, send a uniformly random
The verifier checks whether the received assignment satisfies the formula. The simulator simply sends a uniformly random assignment every time. Writing 


The protocol has perfect soundness and completeness error at most 
A remark about privacy: This protocol reveals a satisfying assignment with overwhelming probability. It is clearly not private in the ordinary sense one would want for a credential or confidential computation. It satisfies MZK because the allowed multiplicative factor is enormous! The rare random branch does the following: it gives the real distribution positive probability wherever the simulator has positive probability. Without it, the simulator could output assignments that the real prover never sends, making pure symmetric multiplicative simulation impossible.
Polylogarithmic leakage: conditional separations much closer to the boundary
An interesting regime lies between logarithmic and polynomial leakage.
For fixed integers 


Two things to note: (i) the argument does not use ordinary uniform SETH, and (ii) the result separates each higher level from SZK; it does not prove that successive levels differ from one another.
Oracle separations in a black-box setting
We prove a separation for every polynomial-time computable, polynomially bounded superlogarithmic integer profile 


The appearance of quantum SZK strengthens the oracle result: even allowing quantum statistical-zero-knowledge (larger than SZK) protocols does not eliminate the separation in the constructed setting.
At polynomial leakage, MZK recovers all interactive proofs
Another result is that

Here, “poly” means the union over polynomial leakage bounds. The equality holds even with zero additive simulation error. PSPACE consists of problems solvable using polynomially bounded memory, potentially with much greater running time! A result of Shamir shows that 
If the prover sends at most 


What remains open?
How sharp is the separation without oracles or computational (nonuniform SETH) assumptions?
Can one prove an unconditional, unrelativized separation at polylogarithmic leakage? Can the conditional results be obtained from weaker or more familiar assumptions? And what is the right characterization of intermediate profiles such as
Is there a strict hierarchy of leakage levels?
In our paper, we give an increasing sequence 
Can intermediate MZK have a natural complete problem?
In my opinion, SZK benefits enormously from Statistical Difference: a complete problem stated simply in terms of two efficiently samplable distributions. Can a similarly clean problem characterize intermediate-leakage MZK?
What are the best efficiency gains within the SZK regime?
For a given task, how much communication can constant or logarithmic multiplicative leakage save? Which savings survive arbitrary redesign of the statistical protocol? Can a conversion to SZK preserve useful bounds on total communication, rounds, or prover computation?
The distributed separation shows that communication savings can be fundamental in an appropriately specific model. Our logarithmic collapse result shows that those savings need not lead to an enlargement of the corresponding public-input proof class. Essentially, can we turn our complexity-theoretic results into useful protocol-design guidance?
References
[1] Shafi Goldwasser, Silvio Micali, and Charles Rackoff. The knowledge complexity of interactive
proof systems. SIAM Journal on Computing, 18(1):186–208, 1989.
[2] Oded Goldreich, Silvio Micali, and Avi Wigderson. How to prove all NP statements in
zero-knowledge and a methodology of cryptographic protocol design (extended abstract). CRYPTO’ 86.
[3] Oded Goldreich, Silvio Micali, and Avi Wigderson. Proofs that yield nothing but their validity
or all languages in np have zero-knowledge proof systems. J. ACM, 38(3):690–728, July 1991.
[4] Amit Sahai and Salil P. Vadhan. A complete problem for statistical zero knowledge. Journal
of the ACM, 50(2):196–249, March 2003.
[5] Daniel Alabi, Marshall Ball. On the Complexity of Statistical and Multiplicative Zero-Knowledge. Cryptology {ePrint} Archive, Paper 2026/2104. https://eprint.iacr.org/2026/2104

